C:\ZYAGA\WORK\LANGFREQ> TYPE README.TXT
LangFreQ
The most common words in a language, counted from what people were actually writing on Twitter, so you could study the top 100 words first instead of 100 random ones.
ERROR 404: HOST OFFLINE. THIS PROJECT IS ARCHIVED, SO THERE IS NO LIVE LINK.
People studying a language are always looking for the most common words: study the top 100 and you're much farther ahead than someone who studied 100 random words. I was studying Japanese and had a hard time finding out which words were the most common, so I built LangFreQ.
It scanned tweets as they came in, recorded every word, and tallied them into frequency lists for English, Spanish, Russian and Japanese. Japanese doesn't put spaces between words, so its list counted kanji instead, against a dictionary of about 2,000 of the most common.
- TYPE
- Word frequency tool
- PLATFORM
- Web · Twitter bot
- YEARS
- 2009 – 2013
- ROLE
- Built all of it: the Twitter indexer, the site and the bot.
- STACK
- Twitter API / Own word indexer
- 4languages: English, Spanish, Russian and Japanese
- 100top words per language, ranked by real use
- 3Twitter bot commands: rank, translate and identify
C:\ZYAGA> DIR /FEATURES 機能
[01]
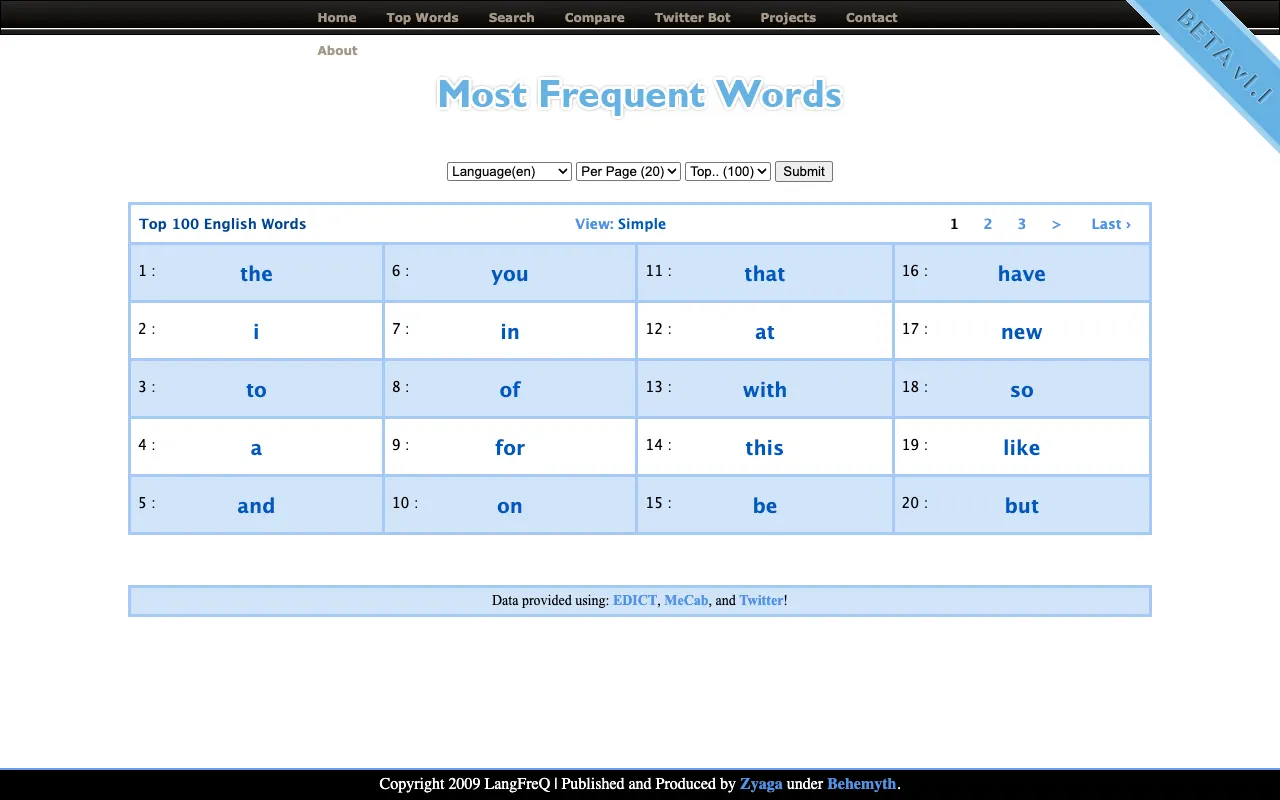
Most frequent words
Pick a language and page through its most used words, ranked from the tweets the indexer had counted.
[02]
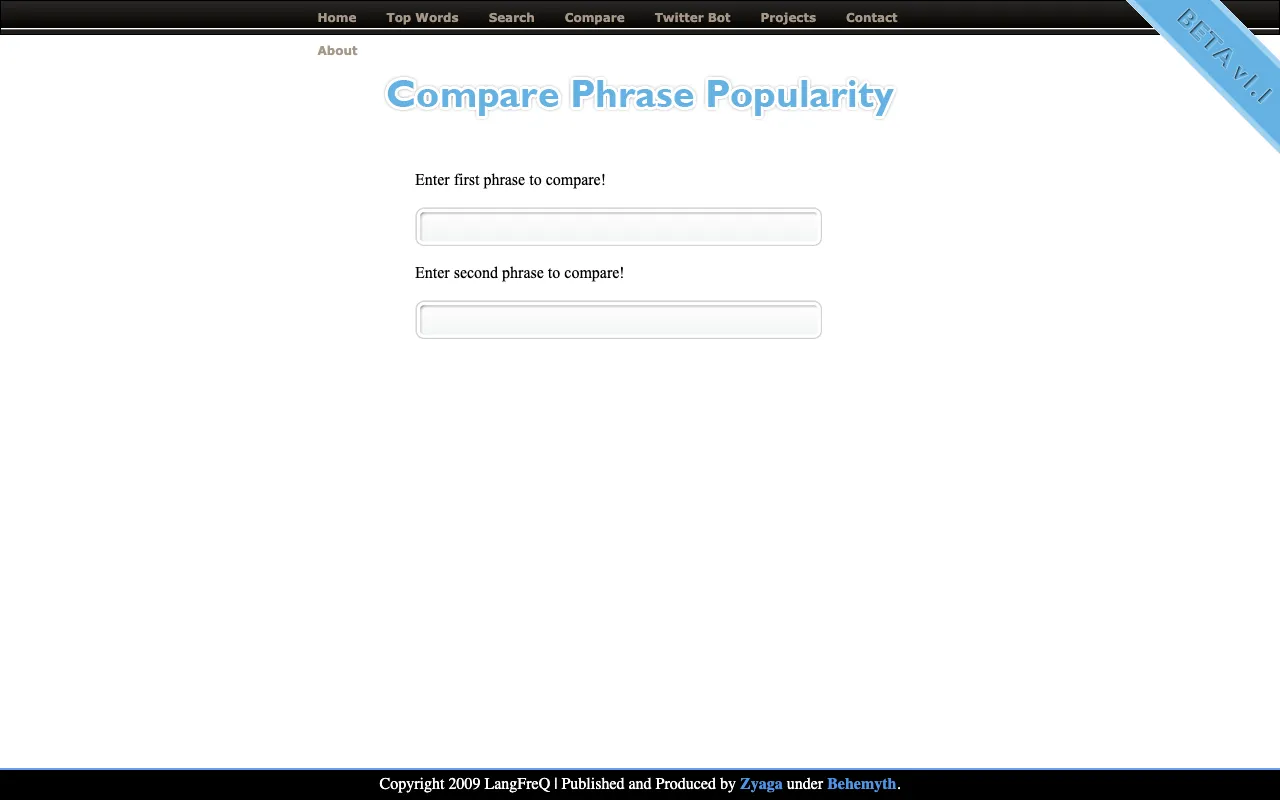
Compare phrases
Enter two words or phrases and see which one people actually use more.
[03]
A Twitter bot
Tweet @langfreq to rank a word in any of its languages, translate a word or phrase, or identify what language something is in.